How AI can learn human language to make our lives easier

Behind the convenience of digital technology that we use every day, such as machine translation, e-mail, search engine. . (e.g., Siri, Alexa, Google Assistant) involve the complexity of machines capable of displaying data, words, images, and videos in milliseconds. Behind this technology, words, sentences, and language are key. How do machines learn human linguistics?
The answer is . (AI). AI technology is one of the future technologies that can change the industry along with the technology ".”, “.", And "cloud”.
As the name suggests, AI technology, or artificial intelligence, is capable of enabling computers to act or make decisions like humans. One aspect of AI is the field of natural language processing (NLP) or natural language processing. This NLP technology enables computers to understand and synthesize text written in human languages.
Although the term NLP is not yet widely known, internet users are already using NLP technology very frequently. It's not just about applications. .which is indeed one of the main targets of NLP technology, NLP technology is also found in various applications used daily.
One that is often used is search engine, like Google, Bing or Yahoo. If we want to search for certain information, we just write the keywords in search engine and in a matter of milliseconds, search engine will display relevant articles.
Another frequently used NLP technology is automatic machine translation (machine translation), seperti Google translateThis feature is often used when reading or understanding a text, or even when writing text in a particular language. ., search engine And machine translation, NLP technology is also frequently used in email filters/short message service(SMS) spam, automatic text proofreader, plagiarism checker, and book recommender (for example on Amazon).
Automated answering machines and sentiment detectors
Currently, in Indonesia, more and more industries are understanding the benefits of using NLP technology. Two types of NLP technology that are widely used by industries in Indonesia are: . and media monitoring.
Chatbot NLP is a technology capable of handling conversations with users automatically. This system attempts to understand user input, whether in text or voice, and then responds accordingly. Many industries are starting to use it. . for various simple functions, such as providing information related to the company or ordering the company's services.
Media monitoring analisis sentimen is an application that uses NLP technology to help extract specific information from various opinions spread across social media. To be at the forefront of a business, a company needs feedbackfrom its customers. When social media was not yet developed, feedback This is obtained through surveys completed by customers.
However, with the growth of social media, this information, in the form of customer opinions, can be obtained through social media. The advantages of using social media over surveys include the accuracy of opinions, which can change over time, faster conclusions, and lower costs.
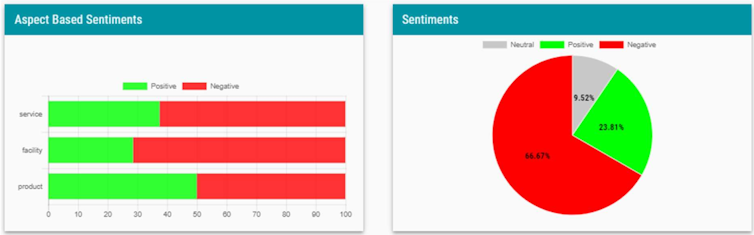
One of the NLP technologies widely used in media monitoring applications is sentiment classification, a technology for automatically categorizing customer opinions as positive or negative. With sentiment classification, we can automatically determine the number of positive or negative opinions about a company's product or service. The image below is an example of sentiment classification results.
How do they work?
Basically, the engineering strategies that are often used in building this NLP technology can be divided into two. NLP processing technique, namely (1) rule-based strategies that are manually written by humans (rule based technique) or (2) rule-based strategies that are automatically derived from data (statistical based technique or machine learning based technique).
The first technique is used if the rules are easy to write. In filter applications SMS spam, for example, the first technique is implemented by data technicians by writing filter words that are classified as spam. Contoh kata penanda spam: (1) congratulations, you got it, (2) need a loan?, (3) let's subscribe with… and others. In this context, a rule is made that if a short message contains more than 5 marker words spam, then the message can be declared as junk information.
The weakness of this first technique is that it is not accurate for handling complex problems, for example complex sentence structure patterns or those containing... unknown word (words that are not on the word list). This is what encouraged the development of the second technique, machine learning based technique. In this technique, various rules (including a list of important words) are obtained automatically through the data.
The first step for scientists to use the technique based on .is to create training data. Quality training data is one of the keys to the success of a NLP application. The following is an example of training data for classification. spam:
“This is mom, I lost my phone card, so I’m using this number. Please send credit to this number” → marked as “SMS spam”.
“Sis, can you send me credit, my credit is almost finished, I need to call you” → marked as “SMS not spam”.
After the training data is built, the scientist then uses the algorithm .to automatically extract a list of important words and other rules from the training data.
Various algorithms . traditional can be used like decision tree, SVM. XGBoost. The algorithm has been developed by statisticians and computer scientists. In addition, the algorithm is also used ., namely the development of the algorithm neural network. Algoritme . This has been proven by many studies to have better performance than using algorithms. . tradisional.
In the technique based on ., quality training data (data in the form of words/sentences) plays an important role in building an accurate model. For this approach unsupervised learning (training data without labels), training data can be easily collected because it does not require special labeling. This means that the system or researchers have not had time to label what one word/sentence is spam or not, for example in the case of SMS spam.
But for the approach supervised learning (training data with labels) such as classification examples SMS spamPreparing high-quality training data requires dedicated effort. The availability of this training data is a particular problem in Indonesia.
Currently, Indonesian computer science researchers are collecting their own training data. There is currently no large, high-quality training data set for Indonesian language NLP. Therefore, in 2016, the Indonesian Association for Computational Linguistics (INACL) or also called the Indonesian Computational Linguistics Society (MALKIN), one of whose goals is to build Indonesian language data that can encourage the progress of Indonesian NLP research.
If the various Indonesian language training data is sufficient, the Indonesian NLP research will progress, promoting various Indonesian NLP products so that our life affairs will be increasingly easily served by artificial intelligence machines.
Written by Dr. Eng. Ayu Purwarianti, ST., MT. . Muhammad Gaffar contributed to the writing of this article.